Tag: Artificial intelligence

  • How AI is transforming insurance

    2023 is the year artificial intelligence went mainstream for work, study and play. The insurance world has been quietly realising AI’s potential for years – to improve customer experience, increase efficiency and reduce costs. We explore what AI is bringing to the industry and where insurers can seize opportunity.

    Applications for AI in insurance span a range of operational areas, from pricing and underwriting through to customer interactions and claims processing. We break down how AI is being applied in key areas, where we’re seeing the biggest developments and what’s next for insurers.

    Boosting efficiency, accuracy and possibility in underwriting

    AI-led improvements in underwriting efficiency and practices are helping insurers boost sales opportunities by reducing the turnaround time for quotes, and improve risk assessment to support better pricing and profitability. In personal lines, where most customers purchase directly from an insurer, AI helps reduce the number of questions required in quote forms and, in certain cases, pre-fills questions. United States insurer State Farm and local player Suncorp, for example, use machine learning applied to geospatial images to streamline home insurance quoting and tie characteristics of the property to potential losses.
    AI helps reduce the number of questions required in quote forms and can sometimes pre-fill questions

    For commercial lines, where much of the underwriting process is manual, AI helps rapidly extract relevant information from documents. In the US, Liberty Mutual is demonstrating the benefits by applying natural language processing to documents to quickly extract relevant information to underwriters. This supports their conversations with brokers and customers, and halves the time required to extract loss data for mid-size and large accounts.

    More streamlined, effective claims assessment

    Image recognition helps simplify and streamline claims assessment, and supports enhanced digitisation of customer experience. This includes Aviva UK’s use of property and motor vehicle damage images to estimate repair costs, and IAG Firemark Venture’s recent investment in Ravin AI, an Israeli tech start-up. Ravin AI produces automated motor vehicle damage and repair cost estimates, which are based on customers’ mobile phone images.

    Moving beyond image recognition, natural language models, including large language models, are helping to extract relevant information from claims forms and notes. This increases the efficiency and effectiveness of claims teams, who can focus their time on claims requiring closer human review. For example, United Kingdom insurer RSA is applying this technology to claims from its pet insurance portfolio, automating the reading and extraction of relevant data from medical reports, treatments and progress notes.

    Chatbot makeovers for enhanced customer experience

    Most people are familiar with the artificial intelligence chatbot. Following recent advancements in large language models, such as those underpinning ChatGPT, the chatbot has benefitted from significantly enhanced capability and performance. Insurers employ these not only as direct-to-consumer instant messaging platforms to answer simple enquiries but also as ‘in house’ assistants to customer service centres.

    AI supports conversations with brokers and customers, and halves the time required to extract loss data for mid-size and large accounts.

    US-based Allstate Insurance’s ‘Amelia’, for example, leads call-centre employees through step-by-step procedures to help answer a variety of customer questions. Amelia also ‘listens’ to interactions she doesn’t understand, to expand her knowledge. Allstate says the benefits of Amelia include a reduction in the time taken to train new employees, and she’s also helping employees better comply with industry regulations.

    Innovations amid a warming world and a focus on bias

    With predicted investment in AI growing to $200 billion worldwide by 20251, we’re going to continue to see innovations in the insurance field. Budding research into AI for disaster prediction, management and relief is especially relevant for insurers in a warming world, with more frequent and intense weather events. In particular, researchers are developing frameworks that combine pre-disaster images with weather data and trajectory of hurricanes. These provide rapid insights on damage caused by natural disasters, with potential to assist in allocating resources for assessment, repair and disaster relief.

    Another strand of research looks to address potential bias and inequities introduced by AI pricing models. Discrimination-free pricing, for example, seeks to produce pricing models that avoid direct or indirect discrimination based on protected features such as gender, while maintaining overall model performance. This has been motivated in part by European Union regulation banning pricing discrimination based on protected attributes. We expect bias and fairness to become a focus of pricing models more globally, as insurers respond to rapidly developing government regulations and directives on the use and application of automated decision processes.

    Exciting times ahead, but risk management key

    While insurers have a lot to be excited about with the current and emerging uses of AI, it’s also a time to ensure systems and processes help them navigate the challenges posed by its use. AI processes can be brittle, exposing insurers to financial, regulatory, legal and reputational risks. Examples include financial losses driven by ‘rogue’ underwriting or pricing algorithms, legal penalties from breaches to customer privacy requirements and loss of goodwill from inequitable treatment of customers.

    Insurers will need to ensure their risk management practices are appropriately structured to incorporate, manage and mitigate AI-specific risks and provide a firm basis for meeting increasing regulatory and compliance requirements. These include impending government regulation on artificial intelligence and significant expansion of requirements under the Privacy Act. By expanding the legislation, the government aims to capture a much broader range of data-related practices, and increase customer rights to control how their data is used and stored.

    This article first appeared in RADAR FY2023, Taylor Fry’s annual roundup of Australia’s insurance landscape.
  • How AI will be impacted by the biggest overhaul of Australia’s privacy laws in decades

    After receiving more than 500 submissions, the Attorney General has released the Government’s much-anticipated response to the consultation process for amending the Privacy Act 1988 (Cth). With the Government’s commitment to introduce legislative changes in 2024, we explore the key proposed changes that may impact AI and outline how organisations who use AI can prepare for these changes.

    In a significant move to address concerns around consumer privacy protections, Attorney-General Mark Dreyfus has unveiled the Government’s response to the Privacy Act Review Report (the Review Report) which looks to bring Australian privacy laws in line with the rest of the world. As discussed in our previous article, we anticipate these proposed legislative amendments are likely to have fundamental impacts on the ways in which organisations are able to collect and use data within AI, machine learning and related processes.

    We outline the key proposed changes that may impact AI and related processes, which the government has either agreed to or agreed to in principle, covering:

    • Expanding the scope of data that is considered to be personal information
    • Expanding consumer rights particularly around consent, use of data and rights of erasure and explanation
    • Requiring that the use of personal information is fair and reasonable.
    Proposed changes are likely to impact how organisations collect and use data within AI

    Expanding what’s personal

    Several proposed changes to the Privacy Act seek to materially increase the spectrum of data that is considered to be personal information, capturing a far broader range of data that is often used in AI and related processes. The Government has agreed in principle to all of these changes, notably:

    • Proposal 4.1 significantly expands the range of information considered to be personal information by changing the requirement for data to be “about” an individual to simply being that it “relates to” an individual. This potentially captures most of the data that can be attached to an individual customer, though the Government has indicated that the Office of the Australian Information Commissioner (OAIC) will issue guidance to confine the connection to situations where it is not “too tenuous or remote”.
    • Proposal 4.3 expands the definition of “collection” to include inferred or generated data. The “inferred” aspect of this action is likely to capture a wide swathe of model outputs, subjecting them to materially increased governance requirements.
    • Proposal 4.9 (c) clarifies that sensitive information can be inferred from not sensitive information, subjecting it to enhanced protections and further complicating AI and data governance. For example, social media interaction data is not necessarily itself sensitive, but the outputs of models that use this data to infer features such as political opinions will likely be captured.

    Taken together, these changes suggest organisations will likely need to significantly expand the reach and structure of their data governance practices, and carefully consider the nature of inferences being made by models, and how these inferences are governed and protected.

    Enhancing consumer rights

    A second category of proposed amendments to the legislation aims to provide greatly enhanced rights to consumers, in line with international trends such as the General Data Protection Regulation (GDPR) legislation in the EU.

    Some of the proposed changes would provide significantly enhanced rights for consumers to determine how their data is used, including through more nuanced rights to provide and withdraw consent, and the right to erasure of personal data. Specifically, the Government has agreed in principle to the following proposals:

    • Proposal 11.1 amends the definition of consent to provide that it must be voluntary, informed, current, specific and unambiguous. Of these aspects, the “specific” component is likely to be of most interest for organisations who make wide use of customer data across multiple functions and processes, potentially requiring consent for the specific use cases.
    • Proposal 11.3 expressly recognises the ability for customers to withdraw consent, and to do so as easily as the provision of consent.
    • Proposal 18.3 provides a right for erasure of personal information on request from an individual, subject to some exceptions around public interest and various technical exceptions.

    Some customers’ consent profiles will change over time and across use cases. The above proposals potentially establish requirements for careful tracking of exactly where individual customers’ data is used and the development of mechanisms to remove the data from processes where consent has been withdrawn. Moreover, there’s a question as to how far the requirement to delete information extends. For example, it is unclear whether the legislation would require AI models that have already been trained on customers’ data to be trained to “unlearn” it within the model. Depending on the model and data structure, such a requirement may introduce significant compliance challenges. As discussed in a previous article, a growing body of research seeks to address these challenges, though technical limitations remain.

    Changes provide enhanced rights for consumers to determine how their personal data is used

    A second class of proposals provides enhanced rights for consumers to receive explanations for how their data is used, including its use in automated decision-making processes, such as those built around AI.

    • Proposal 18.1 provides a right for individuals to access, and to an explanation about, their personal information if they request it, with Proposal 18.1(c) including a requirement that the organisation provides an explanation or summary of what has been done with the personal information.

    Proposals 19.1, 19.2 and 19.3 set out more explicit rights to explanation for substantially automated decision procedures that have a “legal or similarly significant impact” on an individual’s rights, including a right to request “meaningful information” about how these decisions are made. Importantly, the Government has agreed to these proposals (compared to the less committal agreement ‘in principle’ for other proposals). The details underpinning these are passed to the OAIC to develop guidelines, and the Government notes an intention to align with the AI regulation under development by the Department of Industries, Science and Resources. We note that there are two key uncertainties in these requirements:

    1. What counts as a “legally or similarly significant effect” – the original consultation paper noted a potentially wide range of cases including decisions in relation to insurance underwriting, access to credit and heath care service allocation – it will be up to the OAIC to clarify.
    2. What is construed as a “meaningful explanation” of how the decision was made. For example, whether a high level discussion along the lines of “we consider a range of factors including x,y,z” will suffice or whether much more explicit and detailed information is required along the lines of which individual factors contributed to the decision and the extent to which they contributed.

    Fair and reasonable use

    Several of the proposed changes, which the Government has agreed to in principle, provide more explicit requirements on organisations to consider the use of personal information in each use case. Specifically:

    • Proposal 12.1 requires that the collection, use and disclosure of personal information is “fair and reasonable in the circumstances”.
    • Proposal 12.2 clarifies the considerations that need to be made in determining whether a use is fair and reasonable in the circumstances. Of these, we point out part (c) that states “whether the collection, use or disclosure is reasonably necessary or directly related for the functions and activities of the agency”.

    Under these proposed changes, organisations would be prudent to have a careful approach to selecting features for inclusion in models, that includes a “fair and reasonable” aspect on top of more statistical bases for selecting model features.

    Organisations would do well to prepare for these changes by reviewing how they capture, process and use customer data throughout existing and planned AI, machine learning and automated decision-making processes

    What organisations should be considering

    The Response to the Report highlights the changes that are likely to come with reforms to the Privacy Act, though many of the details still need to be refined through focused consultation in the lead up to introducing the updated legislation in 2024. Nevertheless, the Government has provided some clear signals around how the legislation is likely to shape up.

    Organisations would do well to prepare for these changes by reviewing how they capture, process and use customer data throughout existing and planned AI, machine learning and automated decision-making processes. In particular, they should:

    1. Audit their AI and machine learning processes under the new definitions of personal information.
    2. Assess if data flow within these processes meets the “fair and reasonable” criteria and minimise unnecessary data uses.
    3. Evaluate processes against the “legally significant” benchmark and ensure decision transparency.
    4. Update data consent tracking systems to comply with the new requirements where required.
    5. Review and, where needed, amend guidelines for future development of AI, machine learning and substantially automated decision procedures to continue providing “privacy by design” guarantees.

    Visit our Ethical AI and Governance page

    For more information on the services we offer to support organisations ensure  AI, machine learning and automated decision-making processes are fit-for-purpose, compliant and build customer trust.

  • Gender bias in AI and ML – balancing the narrative

    In support of this year’s International Women’s Day theme Cracking the Code: Innovation for a gender equal future, statistics expert and Taylor Fry Director Gráinne McGuire looks at the issues impacting gender parity in this age of digital transformation. Driven by her passion and advocacy towards the ethical use of machine learning (ML), Gráinne explores the inherent gender bias in artificial intelligence (AI) and what can be done to close the gender gap.

    “Man is to computer programmer as woman is to homemaker?”. So opens a paper I came across recently. It seems to me to perfectly encapsulate the problems with gender and AI. Not that there’s anything wrong with either job – what’s wrong is the gendered association. Combine that with AI and ML being increasingly applied at scale and in a position to not only predict the future, but also create the future and reinforce biases, and we’re into Cathy O’Neil’s Weapons of Math Destruction territory.

    If data is biased, AI and ML tools amplify the biased patterns, such as woman = nurse

    We know we’ve got problems with AI and gender. AI relies on lots and lots of data. This data comes from our lived experiences and our world is biased. And AI isn’t really all that smart – it just pretends to be by being really good at finding patterns in data and using those to infer or predict things about the world. And therein lies the problem – AI suffers from bias amplification. You feed in biased data and – no surprise – the AI or ML tool finds the patterns and comes up with man = doctor, woman = nurse. Or the one above, which isn’t necessarily all that accurate.  Women were prominent in the early days of computer programming after all – with the likes of Ada Lovelace, often regarded as the first computer programmer, and American computer scientist and mathematician Grace Hopper paving the way – until men realised it was cool and important.

    Those in the know might point out that I’m referring to embedding models above and in many ways they are the larvae to ChatGPT’s butterfly (related, but utterly different and so much upstaged by ChatGPT), but ChatGPT can fall prey to the same thing (although the ChatGPT creators do appear to have deeply considered gender bias – still, it’s hard to catch everything).

    Real-life examples of gender bias in AI

    Profession gendering

    In a recent article for Fast Company, Textio cofounder Kieran Snyder asked ChatGPT to write feedback for someone in a particular job with no gender specified. Often the feedback was gender neutral but stick nurse or kindergarten teacher into the mix, or mechanic and construction worker and the she’s and he’s start to appear. You can probably guess which jobs got which pronouns. But at least doctors were always ‘they’ in their tests, so that’s something.

    Racial bias – even famous people are not immune

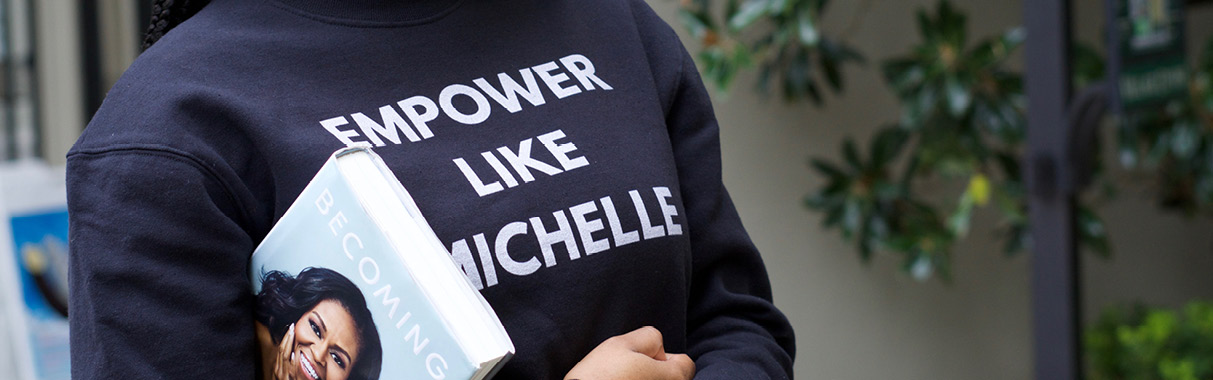
    Of course, it’s not just language models that suffer from bias and specifically bias against women. We see it in facial recognition software, particularly if you’re a black woman. MIT graduate, Joy Buolamwini’s research paper uncovered large gender and racial bias in automated facial analysis algorithms. Given the task of guessing the gender of a face, the systems performed substantially better on male faces than female faces, with error rates of no more than 1% for lighter-skinned men, compared with error rates of up to 34.7% for darker-skinned females. She called this phenomenon the ‘coded haze’, in which AI systems failed to correctly classify the faces even of iconic women like Oprah Winfrey, Michelle Obama and Serena Williams.

    The’ tech bro’ age

    And coming back to where we started, man is to computer programmer? Well, that’s a contributing factor to the problem. We’ve all seen pictures of the tech bros. Even those of us not in tech but using AI/ML tools in other areas often find ourselves in workplaces that have more men than women. And when people are designing algorithms and thinking about their impacts, with the best will in the world, it’s hard to be a good advocate for someone whose experience of life is very different to yours.

    Bias in facial recognition has seen algorithms fail to classify iconic women like Michelle Obama

    A matter of life and death – why we must act now

    Quite literally, this bias is killing people. Medical data, I’m looking at you. A lot of medical trials are carried out on men only because – you know – women have these awkward hormonal cycles that mess with the results. So, let’s do it on men only and get nice clean results. But, those very same hormones might mean the medicine works differently in women, or their symptoms might be different. Feed that inadequate data into an ML algorithm and the bias goes round and round. Women get inadequate health care or die.

    Invisible women – when prejudice is magnified

    This problem was explored in depth by best-selling author Caroline Criado Perez, who spent years investigating the gender data gap, and wrote the award-winning book Invisible Women. In her new podcast series, Visible women, Caroline uncovered that AI might be making healthcare worse for women because it magnifies the pre-existing bias and data gap caused by overrepresentation of men in cardiovascular research. In fact, according to research funded by the British Heart Foundation, more than 8,000 women died between 2002 and 2013 in England and Wales because they did not receive the same standard of care as men.

    The ‘strong’ vs ‘bossy’ lens

    In a wide-ranging interview with Jacqueline Nolis, a data scientist, I was struck by Nolis’s experiences with performance reviews as a transgender woman before and after transitioning. A well-established data scientist, her reviews went from being described as being “so good at always saying the truth … even in hard situations” and “thank goodness … always speaking out” to – following a job change after her transition – receiving for the first time in her life reviews like “difficult to work with”, “doesn’t know how to speak to other people”, “needs to learn … when to not say stuff”. Is it any surprise we’re losing women from the AI/ML pipeline when many of them face everyday sexism?

    Busting myths one hurdle at a time

    And that’s even assuming they get into the pipeline in the first place. They have to get past the hurdle of studying a STEM field in university, where many women come from a society that says “women just aren’t as good at maths and sciences as men”. This even became a controversial political issue in England in 2022 when the Chair of the Social Mobility Commission discussed why fewer girls take A-level physics, saying “they don’t like it, there’s a lot of hard maths in there that I think they would rather not do”. While not everyone shares that view (the Children’s Commissioner for England countered that it was more to do with the lack of female role models in STEM), it does show that this view is endemic in many societies.

    AI might be making healthcare worse for women … More than 8,000 women died between 2002 and 2013 in England and Wales because they did not receive the same standard of care as men.

    What can be done to close the gap?

    This is hard – let’s not minimise it. But hard is not an excuse for doing nothing.

    Tackle ethics together

    Ethical data standards are a place to start and there are many of these around, but they all (unsurprisingly) share common themes – recognise and manage bias, be fair, consult with those impacted by their use, consider privacy and human rights. However, it’s important to acknowledge the problem with many of these standards is that they don’t tell you how to deal with these issues.

    This point was demonstrated in feedback we received in our one-year review of the NZ algorithm charter (a “commitment by government agencies to manage their use of algorithms in a fair, ethical and transparent way”). Some of the feedback included that not all agencies had sufficient experience in measuring bias or applying human oversight, and they’d appreciate a community of practice to support compliance with the Charter as a whole. So we need to learn from one another.

    Focus on fairness

    There’s much discussion around the concept of fairness out there. But fairness is a complicated problem, with many possible and conflicting definitions. I’ve discussed fairness in the past, so I won’t repeat it here (but if you check out the article, you’ll find an example of gender bias in Swedish snowploughing, as well as a discussion around some issues of fairness).

    If you’re building a model with significant personal impacts, then you may want to consider building an interpretable model, as per another article of mine on the topic. Long story short, if you’re looking to deal with biases, then working with interpretable models can make this a lot easier, since you at least understand why your model makes the predictions that it does.

    Proactive perspective in the workplace

    Consider your staff and get a diverse range of people into the room working on these algorithms, which in turn gives you a diverse range of views on the possible consequences of using them. I’ve observed that the outspoken people on topics of fairness, bias and impact of AI are often women – Cathy O’Neil, Timnit Gebru, Cynthia Rudin, Caroline Criado Perez to name a few. Is this a coincidence?

    The thing is, gender isn’t a minority group, women and men are approximately equal in number. And if AI is biasing against close to half the population, that’s a huge problem we need to solve.

    Understand that self-promotion can be nuanced

    I’m not an HR person so it’s a bit outside my area of expertise to suggest how to do this, but there are some commonsense things we can do – like recognising that, overall, women are more likely to underestimate their abilities, men to overestimate. Or that people may come from cultures where self-promotion may be frowned upon. When making hiring or promotion decisions, we should take that into account.

    Encourage more women in STEM

    Finally (in the sense of this article, not in the sense of solutions to the bias problem!), we’ve also got to get more women into the STEM pipeline – more girls doing STEM subjects at school and university. Again, this is a huge subject in its own right, so I won’t go into details here. But I will note that one of the articles I referenced earlier, discusses recent research by the authors which found that external feedback on mathematical abilities had a significant impact on the likelihood of girls pursuing a maths-requiring STEM degree.

    Crucial flow-on effects of fixing gender bias

    Let me finish by acknowledging that gender isn’t the only thing AI has a bias problem with. Personally, being a cisgender white female puts me in a far better place than many others find themselves. Minority groups in general suffer, some more than others. But we shouldn’t fall prey to whataboutism and use that as an excuse not to fix gender bias because other groups have it worse. What’s more, a large proportion of those other groups who have it worse will be women anyway, so fixing gender bias may just help them out a little bit, too.

    The thing is, gender isn’t a minority group, women and men are approximately equal in number. And if AI is biasing against close to half the population, that’s a huge problem we need to solve.

  • The pandemic – a big win for primary data collection and dashboarding, a loss for AI

    In this edition of Normal Deviance, Hugh Miller looks at some of the literature around the use of Artificial Intelligence (AI) during the COVID-19 pandemic and reflects on some of the challenges in creating useful AI tools.

    The pandemic has brought many issues into sharp focus. One is the public benefit of good data collection and dissemination – what would be termed ‘business intelligence’ in the corporate world. Worldwide resources such as the Johns Hopkins Coronavirus Resource Centre and the Our World in Data coronavirus hub have allowed people to explore up-to-date information and understand how the pandemic is evolving through various peaks and troughs. Most national governments have similarly invested in data collection and reporting. In Australia, the Commonwealth and State governments publish large amounts of detailed information, often daily. This facilitates the research of others too; for instance, much of the more advanced epidemiological modelling relies on this data as a starting point.

    Similarly, the value of good epidemiological modelling has been proven. In Australian organisations such as the Doherty Institute and Burnet Institute have provided advice to government that has directly fed into decisions on the nature and durations of restrictions used to manage the pandemic.

    With these successes, it is natural to ask if the high-tech frontier of data science, AI and machine learning, have played similarly useful roles during the pandemic. Unfortunately, the results are not so flattering.

    One area of research has been the use of predictive modelling to better identify and triage patients with COVID-19. A report by Wynants et al. (2020) in the British Medical Journal reviewed over 200 of these prediction models. Overall, it found that:

    • All models were rated with a high or unclear risk of bias, due to non-representative samples of control patients, sample selectiveness, overfitting and unclear reporting.
    • Only 5% of models were externally validated via a calibration plot (to indicate how the model was likely to perform in the wider world).
    • Just two models were identified as promising models, worthy for further research.

    Therefore, the use of such models as decision support tools is highly problematic.

    Another area of research has been the automatic diagnosis of COVID from scan data (mainly chest x-rays and chest CT scans). A review by Roberts et al. in Nature Machine Learning, who found and reviewed 62 such models. They were even more damning – finding that none of the models were suitable for clinical use due to methodological flaws and biases. Again, the risk of bias was generally high, being based on small (and poorly balanced) datasets, and relatively low rates of external validation. More worryingly, many papers did a poor job at attempting to validate the models, and in one case someone accidently used a subset of their training data as the test! In many studies the proposed performance of a tool was judged optimistic, rather than realistic.

    What should we conclude from these systematic reviews – do they mean a retreat from AI in medical science? Most experts say no, since the opportunities are profound. However, there will need to be significant scrutiny of AI work to earn the trust of practitioners and patients, particularly following the lack of traction seen in the pandemic and the struggles of other healthcare investments such as IBM Watson. Lots of solutions and improvements have been mooted – much of it relates to better data and sharing, more systematic collaboration with clinicians, more work validating and comparing to other models. Much of this relies on researchers themselves to strive for a higher level of quality so that a publishable result can get closer to a useful one.

    And it is important to recognise there have been some other bright spots for AI and big data during the pandemic too. For instance, the Moderna vaccine used AI for mRNA sequence design in vaccine development. Greece used an AI screening system for people entering the country to flag those at relatively low or high risk of having COVID-19, making better use of limited testing resources. And mobility data from tech companies has proven a valuable tool drawn from big data, allowing policymakers an up-to-date forecast of transportation around cities.

    With the success of traditional business intelligence, dashboarding and traditional ‘hard science’, it is fair to say the current pandemic is the first global pandemic truly managed by the numbers. But we’re still a fair way away from being able to rely on AI tools to ride to the rescue.

    As first published by Actuaries Digital, 7 February 2022

  • When the algorithm fails to make the grade

    In our latest article, the story of the UK algorithm to assign high school grades following exam cancellations teaches an important lesson for everyone building models where questions of individual fairness arise.

    There have been many consequences of the pandemic. While health and employment concerns are rightly prominent, education is another domain that has seen significant disruption. One recent story intersecting with modelling and analytics is the case of school grade assignment in the UK. With final year exams cancelled due to the pandemic, the Office of Qualifications and Examinations Regulation (Ofqual) was presented with the challenge of assigning student grades, including the A-level grades that determine eligibility for university entrance.

    Part of the challenge is that centre-assessed grades (grades issued by schools based on internal assessment) are always optimistic overall compared to actual exam grades, so the process required choosing the best way to move grades closer to historical patterns. An algorithm was created to produce predicted grades across the whole student cohort.

    However, when results were posted out there was student outrage at the perceived unfairness of people who received a lower grade than they expected. Pressure led to all governments across the UK backflipping and announcing that centre-assessed grades would be recognised instead of the algorithmic grades. While a win for many students who felt they deserved higher grades, it does raise significant further questions and represents a poke in the eye for those who stood by the robustness of the algorithmic grades.

    In many ways the Ofqual algorithm for adjusting grades ticked all the right boxes:

    • The process was thorough and transparent, with a detailed report released explaining the methodology, alternatives considered and a range of fairness measures to ensure particular subgroups were not discriminated against.
    • The process used available data well, incorporating a combination of teacher-assessed rankings, historical school performance and cohort-specific GCSE (roughly equivalent to our school certificate) performance to produce grade distributions. Such approaches are also used elsewhere. For example, in NSW HSC school assessment grades are moderated down using school rankings so they reflect a cohort’s exam performance.
    • The process gave some benefit of the doubt to students, allowing for some degree grade inflation. For courses and school cohorts where there were only a small number of students, more weight was given to centre-assessed grades.

    However, with the benefit of hindsight, it was clear that effort was not enough. The main factors contributing to the government backdown:

    • The stakes are very high. For many students, the difference between centre-assessed grades and modelled grades is the difference between their preferred university degree and an inferior option (or no university admission at all!). Students have a strong incentive to push back on the model.
    • Accuracy is good, but it was not great. While the report was careful to describe expected levels of accuracy (and choose methods that delivered relatively high accuracy), the reality is that a very large fraction of students got the ‘wrong’ grade, even if the overall distribution was fair. Variability across exams is substantial, and a very high level of accuracy would be required to neuter criticism and disappointment.
    • There were still some material fairness issues. Smaller courses are disproportionately taken by students at independent schools, and under the model these grades were less likely to be scaled back. Thus students attending independent schools were more likely to benefit from leniency provisions.
    • The model unilaterally assigned fail grades to students. The modelling included moving a substantial number of people from solid pass grades into the “U” grade (a strong fail grade, literally ‘ungraded’). There’s a natural ethical question whether it is fair to fail students who were not expected to fail according to their teachers, based on school rates of failure in prior years.
    • Perhaps most importantly, the approach failed to provide a sense of equality of opportunity. If you went to a school that rarely saw top grades historically, and your school cohort’s GCSE results were similarly unremarkable, there was virtually no way that you could achieve a top grade in the model. This does not sit well with students; the aspiration is that any student should be able to work hard and blitz their exams. Instead, students felt that they were effectively being locked into disadvantage, if they had attended a school with historically lower performance.

    Unsurprisingly, the final solution (adopting the centre-assessed grades) will create its own problems. Teacher ‘optimism bias’ is unlikely to be uniform across schools, so students with more realistic teacher grading will be relatively disadvantaged. Teacher grades may be subject to higher levels of gender or ethnic bias. The supply of university will not grow with the increased demand implied by higher grades; in some cases, this may be handled through deferrals which may have knock-on effects for availability for 2021 school finishers. And overall confidence in Ofqual has taken a substantial hit.

    I think there are some important lessons here for data analytics more generally. First, models cannot achieve the impossible; in this case, it is impossible to know which students would have achieved a higher or lower mark. In a high-stakes situation, such limitations can break the implementation of a model. Second, it raises the point that something that appears ‘fair’ in aggregate can look very unfair at the individual level.

    In situations where individual-level predictions have a significant impact, we should spend time understanding how results will look at that granular level, and who the potential ‘losers’ of a model are. Finally, an algorithm will often become an easy target. As we’ve also seen in COMPASS and robodebt coverage, a faceless decision-making tool carries a high burden of proof to establish its credibility; this requirement applies from initial model design through to results and communication. Appropriate use of modelling is something we will need to continue to strive for in our work.

    #InTheNews – “England exams row timeline: was Ofqual warned of algorithm bias?” from @guardian https://t.co/MjCKgyYc9V#NAPCE #pastoralcare #schools #education #teachers #exams #childwelfare #studentwelfare #covid19 #gcses #alevels pic.twitter.com/ruL5QUaBrs

    — NAPCE (@NAPCE1) August 21, 2020

    UK ditches exam results generated by biased algorithm after student protests https://t.co/ZQtWT1iqJe pic.twitter.com/G6RAldar59

    — The Verge (@verge) August 17, 2020

    As first published by Actuaries Digital, 24 September 2020